Complex documents in.Clean structure out.Built with Indian language documents in mind
Convert invoices, financial statements, contracts, and handwritten forms into editable DOCX, structured tables, and production-ready JSON—with zero-retention processing. For Indian language and mixed-script documents, review critical fields against the source.
Field-level
Accuracy Review
Layout-Aware
Table & Hierarchy Preservation
Zero Retention
RAM-Only Processing Guarantee
1.5s – 3.0s
Average Processing Speed / Page
Startup India
DPIIT recognised startup
Cognitive String Private Limited
Deepgram
Collaboration
Collaborating with Deepgram
NVIDIA Inception
Selected for the program
NVIDIA Inception program selection
Watch DocuAILens
From scanned documents to digital clarity
A short introduction to DocuAILens and its approach to document intelligence. Play the video to explore the product.
Indian language documents
Plan for mixed scripts. Review for accuracy.
Invoices and forms in India may combine Hindi, Bengali, Tamil, Telugu and other regional scripts with English. Preserve the source script and check names, identifiers, amounts and table columns against the original document.
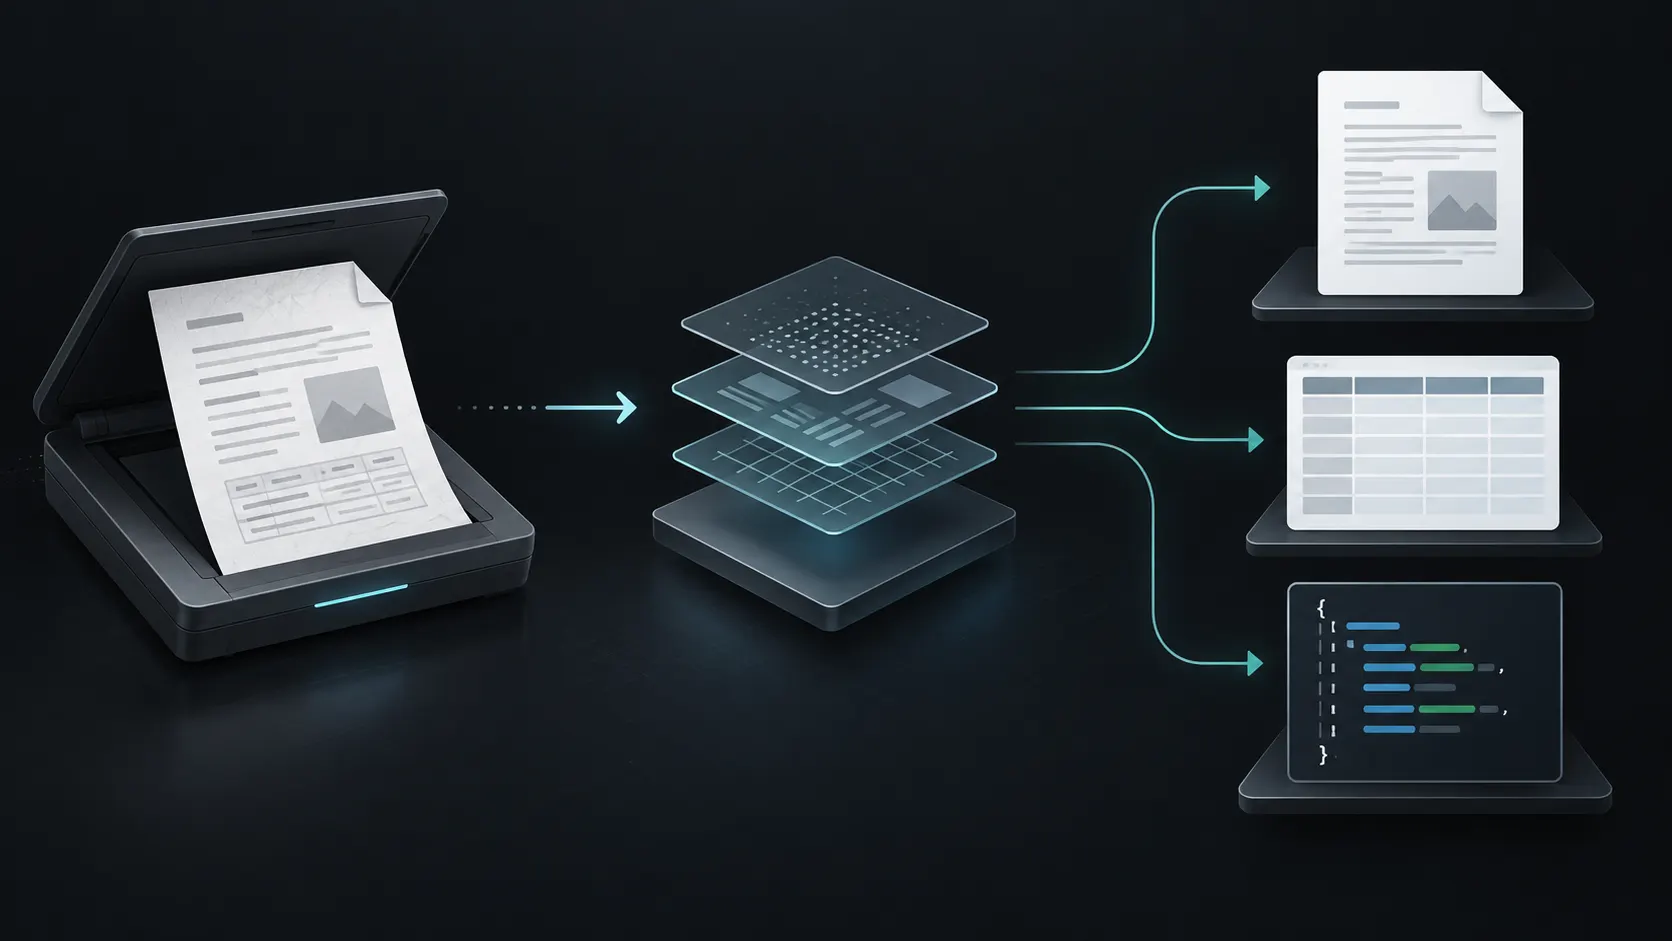
See DocuAILens In Action Across Real Documents
| Extracted Entity / Description | Classification | Rate / Status | Computed Total |
|---|---|---|---|
| Enterprise Cloud Infrastructure - US-East Cluster | 12 | $850.00 | $10,200.00 |
| Cognitive Vision API Dedicated Throughput Pool | 1 | $3,500.00 | $3,500.00 |
| 24/7 Priority Mission Critical Engineering SLA | 1 | $1,150.00 | $1,150.00 |
Demo output is illustrative. For Hindi, Tamil, Bengali and other mixed-script scans, check the original script and critical fields.
Why Traditional OCR Fails Your Business
Flat text can lose table structure and reading order. In documents that mix English with Indian scripts, reviewers should also verify script, names, numbers and the columns those values belong to.
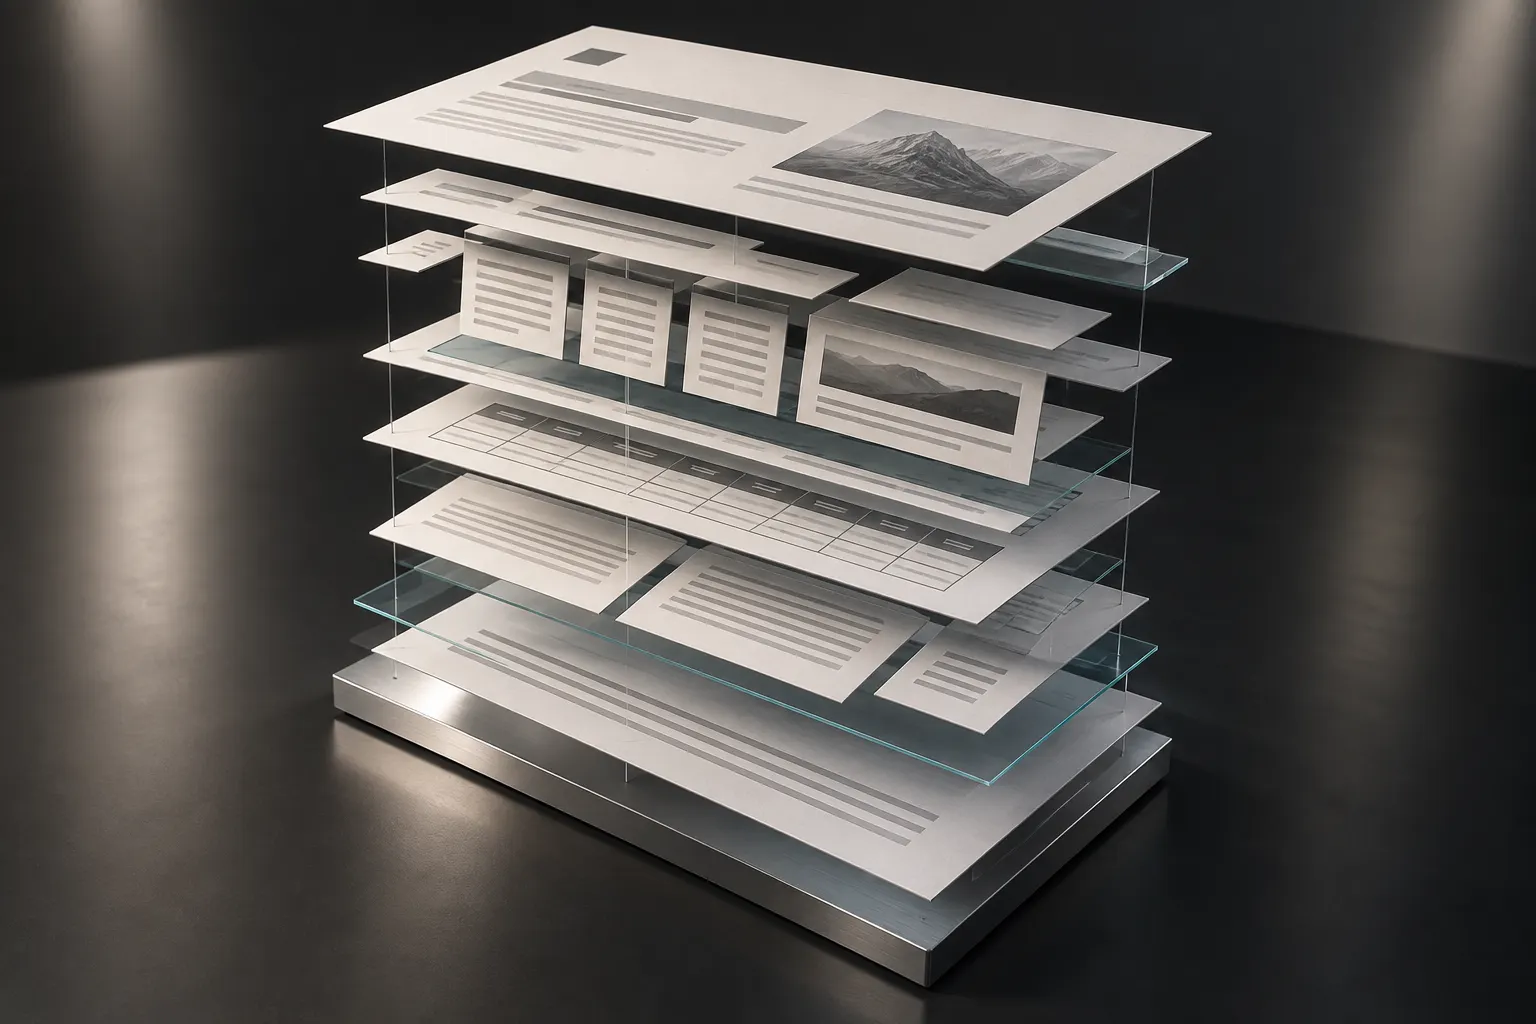
Structure, not just characters
Every column, table, and hierarchy remains a distinct spatial layer.
See the Indian invoice accuracy checklist for field and table checks.
Traditional Flat OCR
Legacy Tech- ✕Flattens tables into disorganized, tab-separated character streams.
- ✕Multi-column reading order gets merged horizontally into jumbled text.
- ✕Outputs raw .txt files that require hours of formatting into Word or Excel.
- ✕Forces documents into public cloud pipelines with uncertain retention.
- Borderless Table Reconstruction: Automatically builds native cells with intact totals and line items.
- Hierarchical Layout Geometry: Preserves headings, sidebars, margins, and paragraph structures.
- Native Microsoft Word (DOCX): Generates fully editable, formatted DOCX files ready for distribution.
- Local Folder Watcher & Zero-Retention: Strict in-memory RAM processing or 100% on-device local execution.
Engineered for High-Fidelity Extraction
Explore document workflows, including how to review mixed English and Indian-language text for accuracy.
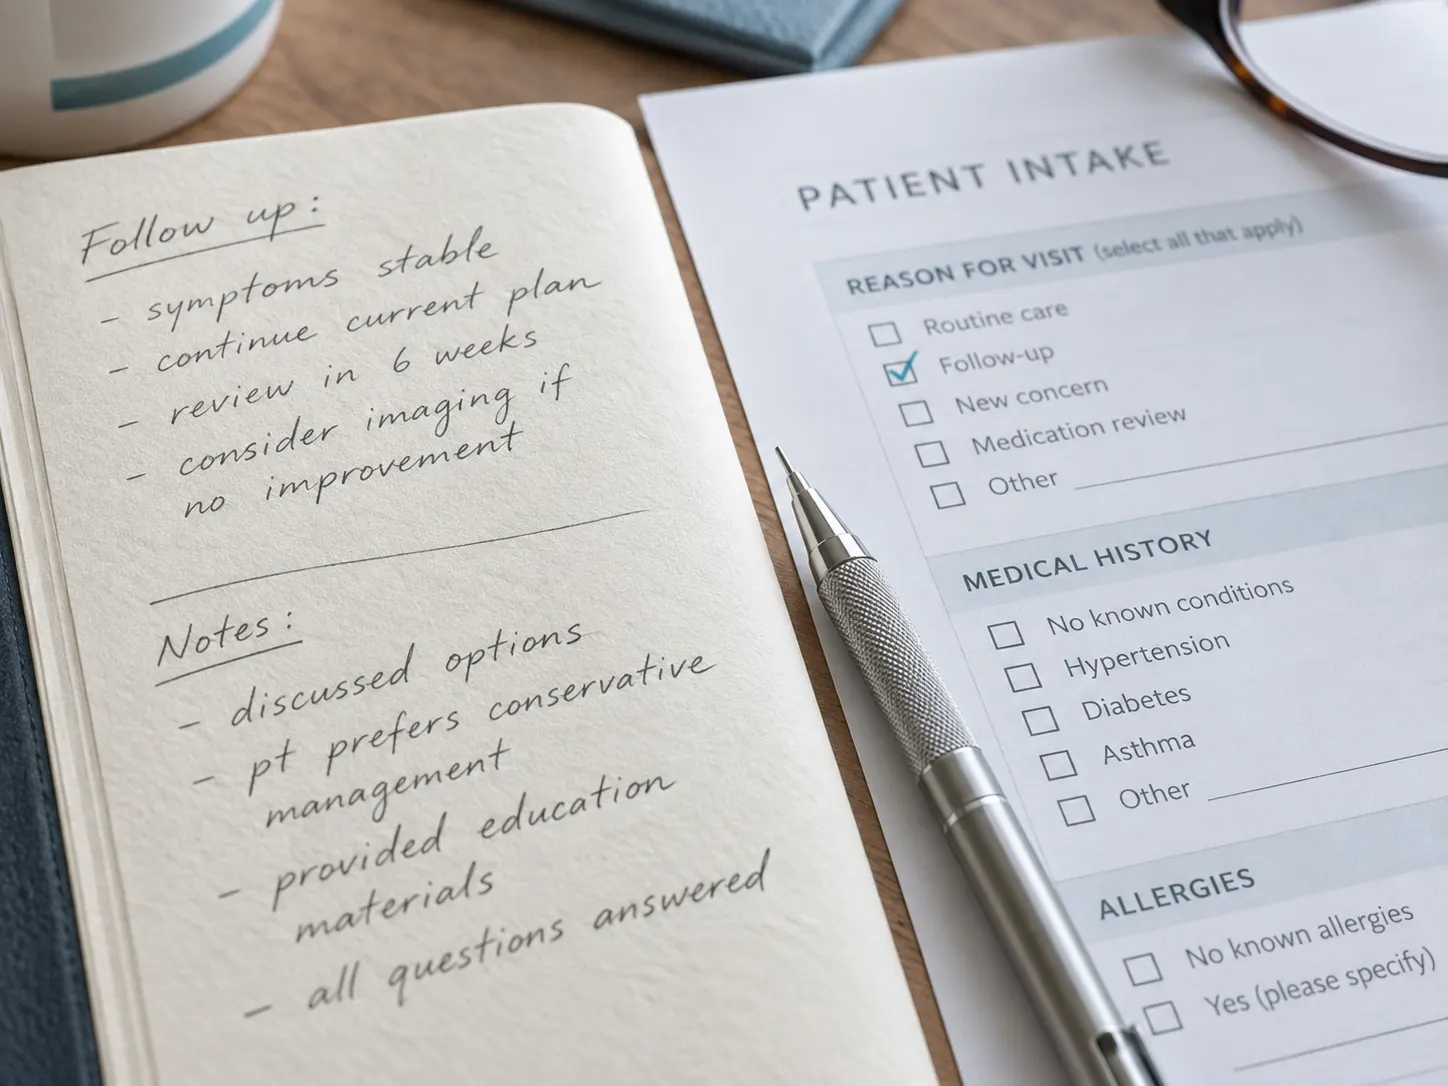
From handwriting to verified fields
Confidence-aware extraction keeps human review focused.
One engine for every document surface.
Printed tables, multi-column reports, form controls, cursive notes, and photographed pages share one consistent extraction workflow.
भारत
Mixed-script review
3
Output types
ZDR
Processing
Layout Geometry Engine
Preserves multi-column reading flow, indentations, headers, and margins without flattening documents into unformatted text strings.
Borderless Table Reconstruction
Detects and reconstructs financial ledgers, invoice items, and grid lines into native structured tables ready for Word and Excel.
Native Word (DOCX) Export
Generates editable Microsoft Word documents with preserved font styling, tables, and paragraphs instead of raw text blocks.
Local Folder Automated Watcher
Process confidential documents directly from your workstation or private server folder. Data stays on your secure network.
Cursive & Form Field Extraction
Extracts legible handwriting, clinical notes, and form checkboxes with confidence scores for human-in-the-loop review.
Indian Language Review
Plan source checks for Hindi, Bengali, Tamil, Telugu and mixed English documents, with close review of names, identifiers and amounts.
Enterprise REST API & SDK
Straightforward REST integration in Python, cURL, or Node.js with webhooks, rate limiting, and structured JSON outputs.
Accessible Document Intelligence Without Enterprise Minimums
Compare plans using your own document samples, including regional-language invoices and mixed-script forms. Start with representative pages and check the fields your team actually uses.
Processing volume
12,840 pages
Meet the Minds Behind the Magic
A team building document workflows for varied layouts, including multilingual business records from India.
Amit Kumar
Founder & CEO
IIT Kharagpur
An alumnus of IIT Kharagpur, Amit is a visionary leader with a passion for leveraging AI to solve complex business challenges. With over 15 years of industry experience, he founded Cognitive String to help businesses unlock their true potential through automation.
Shankar Chaudhary
Founder & MD
Technology & Management
Shankar is a strategic leader focused on driving growth and operational excellence. With a deep background in technology and management, he co-founded Cognitive String to revolutionize business processes through intelligent automation.
Abhishek Sultania
Founder & COO
IIT Kharagpur
An alumnus of IIT Kharagpur, Abhishek is the driving force behind our operations and execution. As Chief Operating Officer, he blends strategic vision with hands-on leadership to ensure seamless delivery of AI-powered solutions and scalable growth across all functions.
Rajesh Kumar
Head of Product
IIM Bangalore
With a strategic mindset honed at IIM Bangalore, Rajesh is dedicated to translating customer needs into powerful features. He bridges the gap between our clients and our development team, ensuring our solutions deliver real-world value.
Sanjay Gupta
Lead AI Engineer
IIT Delhi
Hailing from IIT Delhi, Sanjay is a master of automation and efficiency. His deep knowledge of AI algorithms and workflow optimization allows us to build powerful and reliable automation solutions for our clients.
Frequently Asked Questions
Guidance on layout, privacy, integrations, Indian scripts, and accuracy review.
What is cognitive string?
cognitive string is an AI-powered OCR and document intelligence app that converts scanned PDFs and images into structured, editable outputs such as Word documents, tables, and JSON.
Who is cognitive string for?
It is built for teams that process invoices, bank statements, contracts, forms, handwritten notes, and scanned business records while preserving layout and structure.
Can cognitive string preserve document layout?
Yes. cognitive string focuses on layout-aware extraction, including headings, paragraphs, columns, borderless tables, and page structure that flat OCR tools often lose.
How should Indian language and mixed-script OCR results be checked?
Keep text in its original script and compare names, identifiers, dates, amounts, and table columns with the source document. Measure accuracy on representative samples for each language and document type.
Does cognitive string support private document workflows?
cognitive string supports secure upload and local folder style workflows designed for sensitive business documents and controlled processing pipelines.
Start Transforming Your Scanned Documents
Explore layout-aware document workflows and learn how to review multilingual output before using critical fields.
Start with the Indian language guide to plan review for names, amounts and mixed scripts.